System diagram showing how to reduce LLM API costs in production using caching and model routing
Scaling generative AI applications often leads to runaway API bills. Discover actionable technical strategies to slash production LLM expenses without degrading output quality.
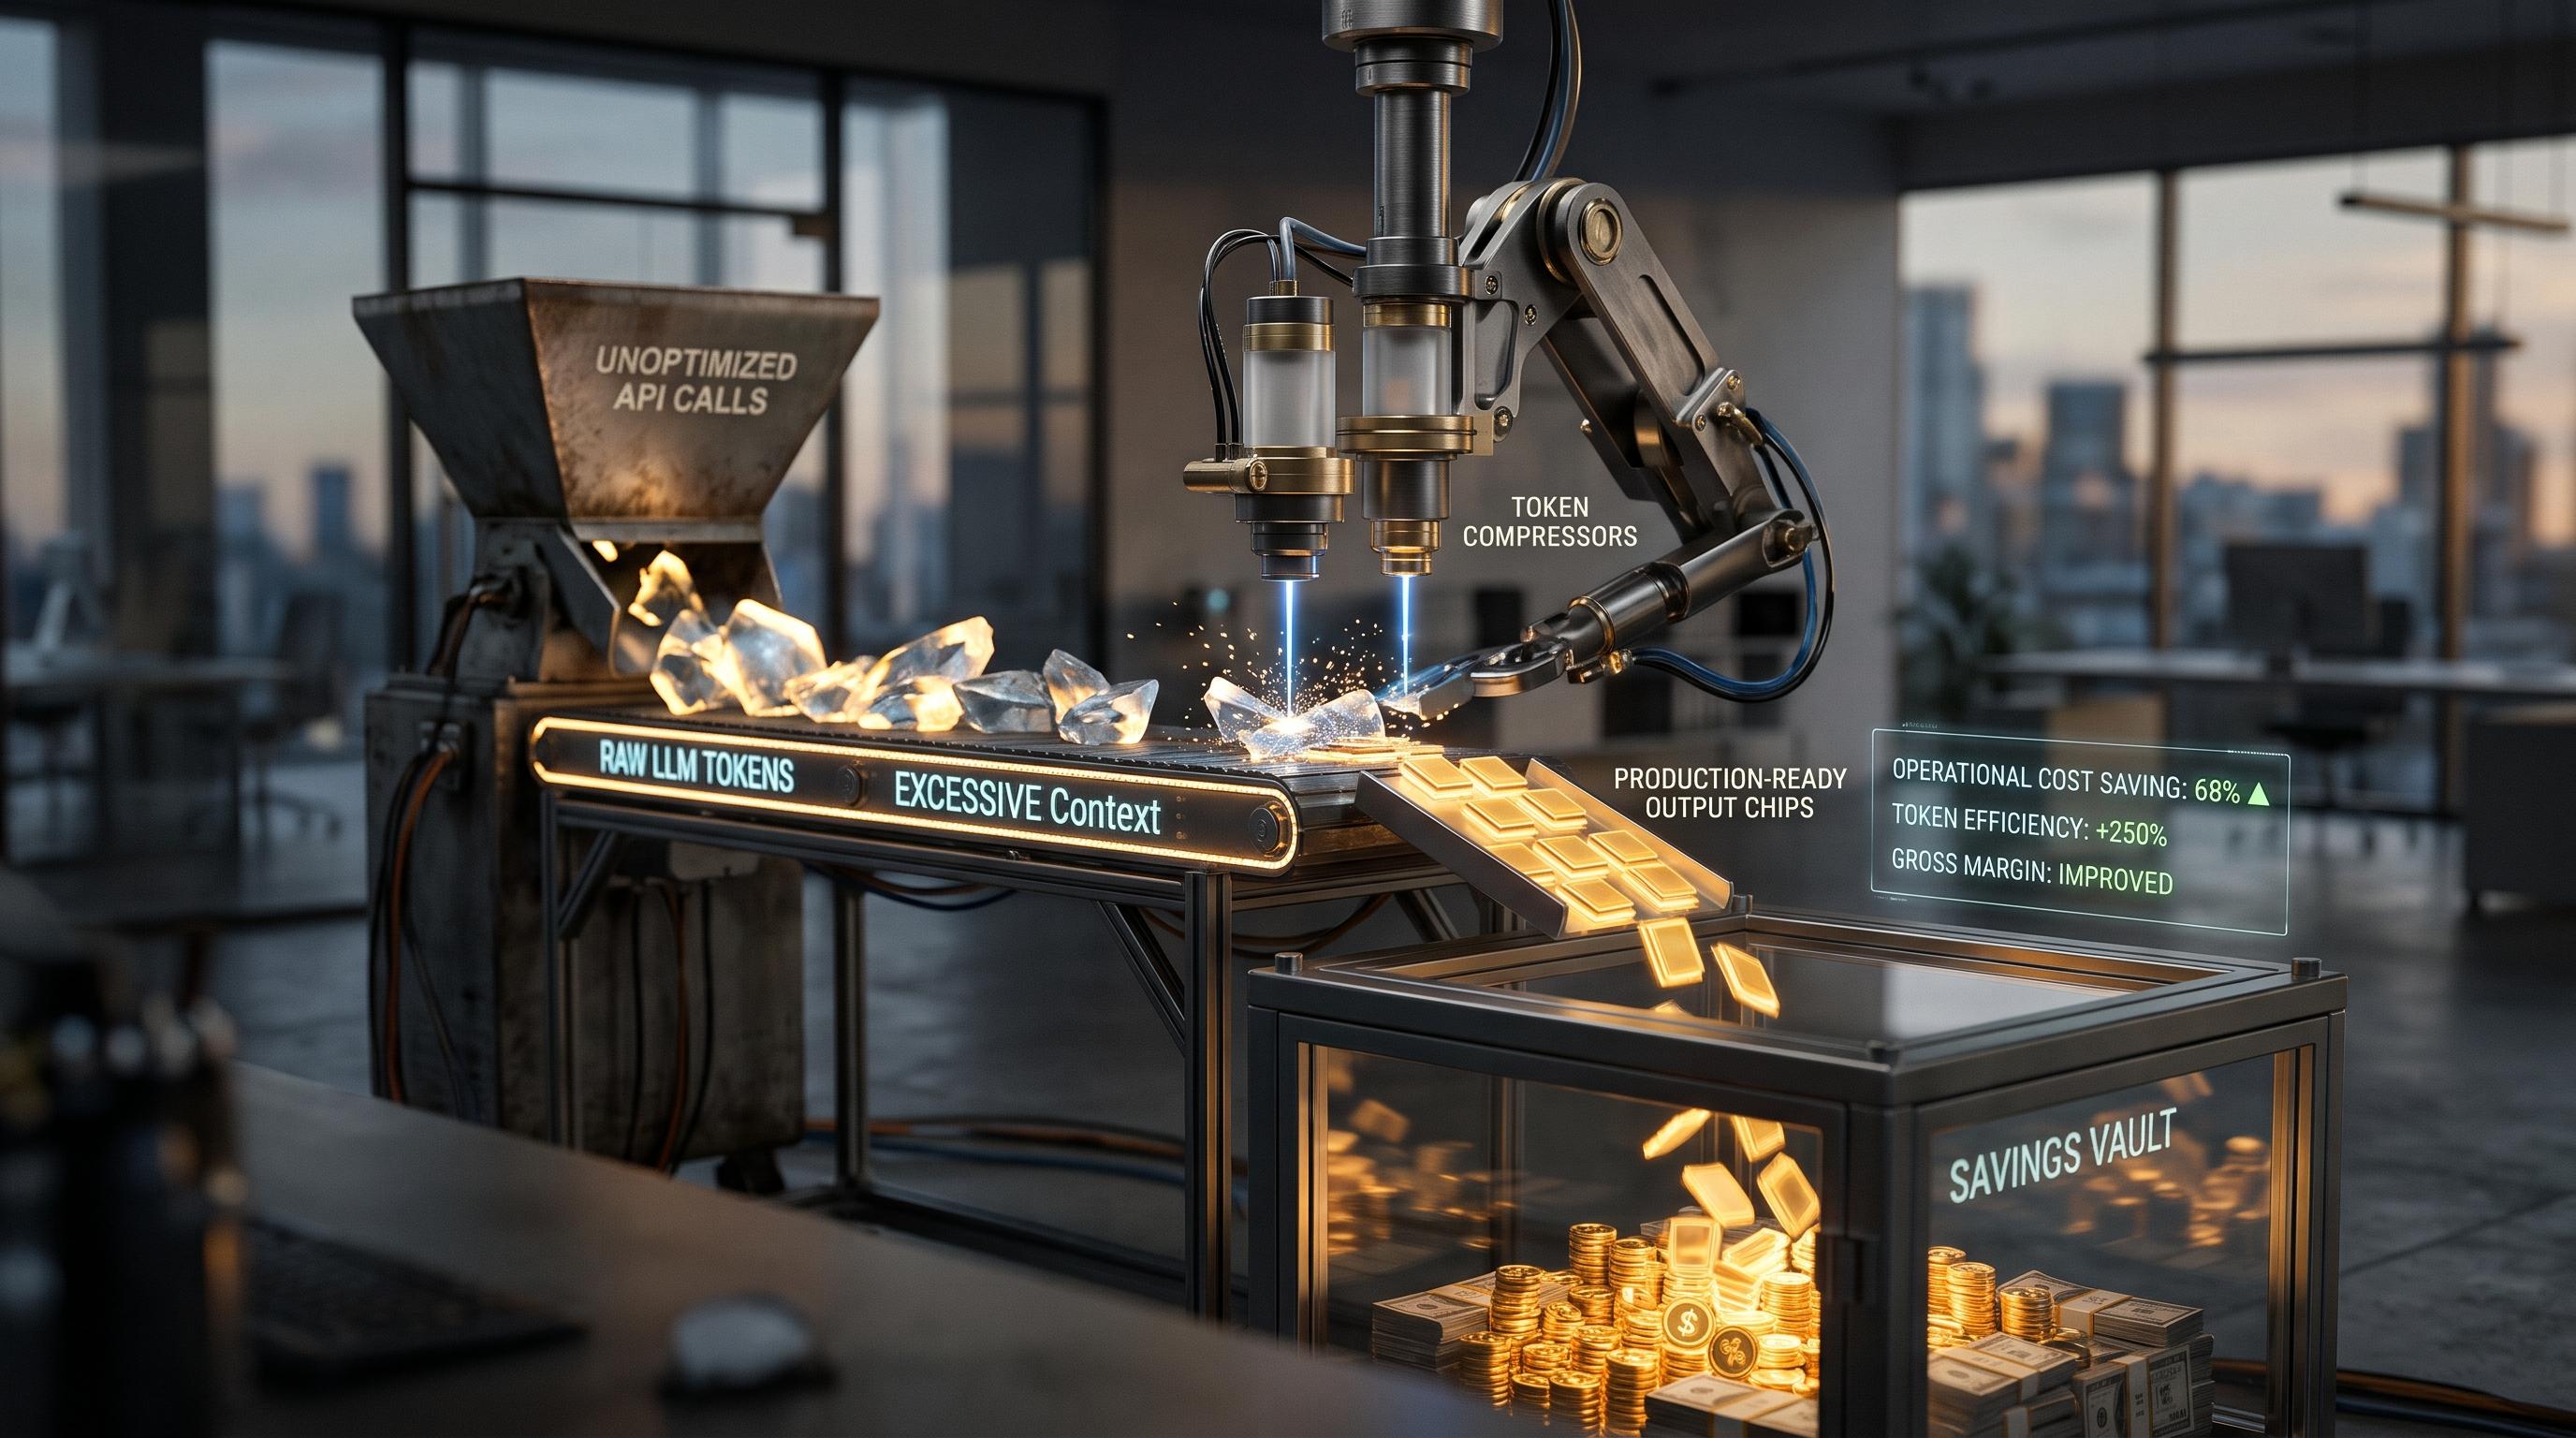
Running generative AI features in a staging environment rarely exposes the true financial friction of large language models. Once real users begin firing queries at your application, token consumption scales quickly. If you are building automated product descriptions, customer support engines, or intelligent catalog systems, learning how to reduce llm api costs in production is critical to maintaining a healthy gross margin.
Controlling model spend does not require degrading output quality. In most applications, high bills stem from poor prompt architecture, redundant API calls, and over-provisioning frontier models for low-complexity tasks. By implementing intelligent routing, caching layers, and aggressive token hygiene, engineering teams routinely trim API expenditure by 50% to 80%.
Here is a complete breakdown of practical, production-ready strategies to cut your LLM expenses.
1. Implement Semantic and Exact-Match Caching
The most cost-effective LLM call is the one you never make. A significant portion of production traffic consists of repetitive requests, recurring user intents, or identical background automation steps.
Exact-Match Caching
For predictable queries, compute a deterministic hash (such as SHA-256) of the system prompt, user payload, and sampling parameters. Store the model response in an in-memory datastore like Redis. If an incoming payload matches the hash, return the stored response immediately. This eliminates token generation costs and reduces latency to single-digit milliseconds.
Semantic Caching
Users rarely type identical sentences, but they frequently ask for the same information. Semantic caching uses vector embeddings to compare incoming prompts against an indexed cache of previous queries.
- Generate an embedding for the user prompt using an inexpensive embedding model.
- Query a vector index to check cosine similarity against previous inputs.
- If similarity exceeds a strict threshold (typically 0.92 to 0.96 depending on your domain), serve the cached response.
- If it falls below the threshold, invoke the LLM and update the cache.
Be cautious with high-variance tasks or personalized data. Reserve semantic caching for catalog questions, technical support FAQs, or documentation lookups where answers remain static.
2. Core Strategies: How to Reduce LLM API Costs in Production with Model Routing
Defaulting every workflow step to a flagship model like GPT-4o or Claude 3.5 Sonnet is the most common cause of inflated bills. Most operational pipelines consist of distinct subtasks: classification, data extraction, summarization, and creative reasoning. Each task has a different performance ceiling.
Model routing directs prompts to the smallest, least expensive model capable of completing the task reliably.
Two-Tier Router Architecture
Instead of sending every raw prompt to a frontier model, deploy a lightweight classifier first:
- Tier 1 (Small Language Models): Use models like Claude 3 Haiku, GPT-4o-mini, or Mistral 7B to classify intent, extract JSON keys, or handle basic input validation. These models cost a fraction of top-tier counterparts.
- Tier 2 (Frontier Models): Route requests to larger models only when the intent classifier flags complex reasoning, nuance, or multifaceted technical evaluation.
If 70% of incoming queries are simple navigational or data-formatting tasks, tiering instantly cuts the majority of your inference expenditure.
Fallback and Escalation Logic
Configure your pipeline to start with the lower-tier model. Validate the output programmatically (for example, verifying schema compliance with Pydantic). If validation fails or confidence scores fall below your benchmark, escalate the payload to the frontier model. You only pay for premium compute when cheaper alternatives fail.
3. Strict Token Hygiene and Prompt Engineering
LLM providers charge per token, counting both input context and output generation. Bloated system prompts and uncontrolled outputs quietly compound operational costs on every request.
Strip Static System Context
Many developers maintain multi-page system prompts filled with redundant examples, defensive warnings, and conversational filler. Audit your system messages regularly:
- Remove conversational phrasing ("Please act as a helpful assistant").
- Replace verbose few-shot examples with compact, structured input-output pairs.
- Use short, explicit constraints instead of long negative prompts.
Constrain Output Lengths
Output tokens are significantly more expensive than input tokens across almost all API pricing structures. If your application only requires a status code or a one-sentence summary, enforce hard limits:
- Set
max_tokensdefensively to prevent runaway generations. - Use structured outputs (JSON schemas or function calling) so the model does not produce conversational preamble like "Here is the data you requested:".
- Instruct the model to return concise responses without pleasantries.
While optimizing context, make sure you do not strip out critical security guardrails. System prompts still need to defend against manipulation, as detailed in our guide on how to protect your online assets from automated threats.
4. Leverage Batch APIs for Asynchronous Workflows
Real-time interactive chat demands sub-second responses, but background workflows do not. Workloads such as nightly catalog updates, bulk inventory categorization, internal reporting, and automated content generation can run asynchronously.
Leading model providers offer dedicated Batch APIs that process non-urgent payloads within a 24-hour window at an automatic 50% discount.
To adopt batch processing:
- Collect jobs into JSON Lines (JSONL) files throughout the day.
- Submit the file through the provider's batch endpoint.
- Poll for completion or handle webhook callbacks to ingest processed outputs.
Shifting non-interactive workloads to batch endpoints halves your costs for those tasks with zero code alterations to the underlying prompts.
5. Fine-Tune Smaller Models for Domain-Specific Tasks
Prompt engineering on massive models is fast for prototyping, but expensive at scale. When you pass hundreds of examples in the context window to force a frontier model into compliance, you pay for those input tokens on every single run.
Fine-tuning allows you to bake that domain knowledge directly into the weights of a much smaller model:
- Collect 500 to 2,000 clean, verified completions from your production logs.
- Fine-tune a lightweight model (such as a 7B or 8B parameter architecture).
- Drastically reduce the system prompt: the fine-tuned model already understands your formatting, tone, and edge-case handling.
A fine-tuned smaller model operating with a 50-token system prompt will routinely outperform a massive general-purpose model burdened with a 2,000-token prompt, running faster and costing substantially less per execution.
6. Monitor, Benchmark, and Set Hard Thresholds
You cannot optimize what you do not measure. Integrate an LLM observability layer (such as Langfuse, Helicone, or OpenLLMetry) into your application stack.
Track these key operational metrics:
- Cost per user session: Identify whether power users are creating unsustainable cost spikes.
- Input-to-output token ratio: Spot prompts with massive context overhead relative to their output value.
- Cache hit rate: Ensure your similarity thresholds in semantic caching are generating returns without producing hallucinations.
- Latency vs. cost trade-offs: Confirm that cheaper models are meeting your user experience SLAs.
Set hard spending caps and automated alerting at the API provider level to prevent unexpected infinite loops in recursive agent architectures.
---
If you want to audit your automation architecture or deploy high-efficiency AI systems, XEONTRIX designs custom automated workflows, voice agents, and digital assets built for enterprise scale. You can schedule a free 30-minute AI strategy consultation with our technical team to optimize your operations.
Questions people ask
What is the difference between exact-match and semantic caching for LLMs?
Exact-match caching stores responses based on an identical hash of the prompt and parameters, returning results instantly at zero model cost. Semantic caching uses vector embeddings to identify queries with similar meaning, allowing different wordings of the same question to use a cached response.
How much can model routing reduce LLM API expenses?
Model routing typically reduces API costs by 40% to 70%. By sending low-complexity tasks like classification and formatting to small models and reserving frontier models for deep reasoning, you minimize token spend across high-volume pipelines.
Are output tokens more expensive than input tokens?
Yes. Most major LLM providers charge between three to four times more for output tokens than input tokens because generating tokens sequentially requires more continuous GPU compute than processing inputs in parallel.
When should a business switch from prompt engineering to fine-tuning?
Consider fine-tuning when you have a stable dataset of consistent tasks and find yourself repeatedly passing large few-shot context windows to large models. A fine-tuned smaller model can drastically cut prompt size and inference fees.